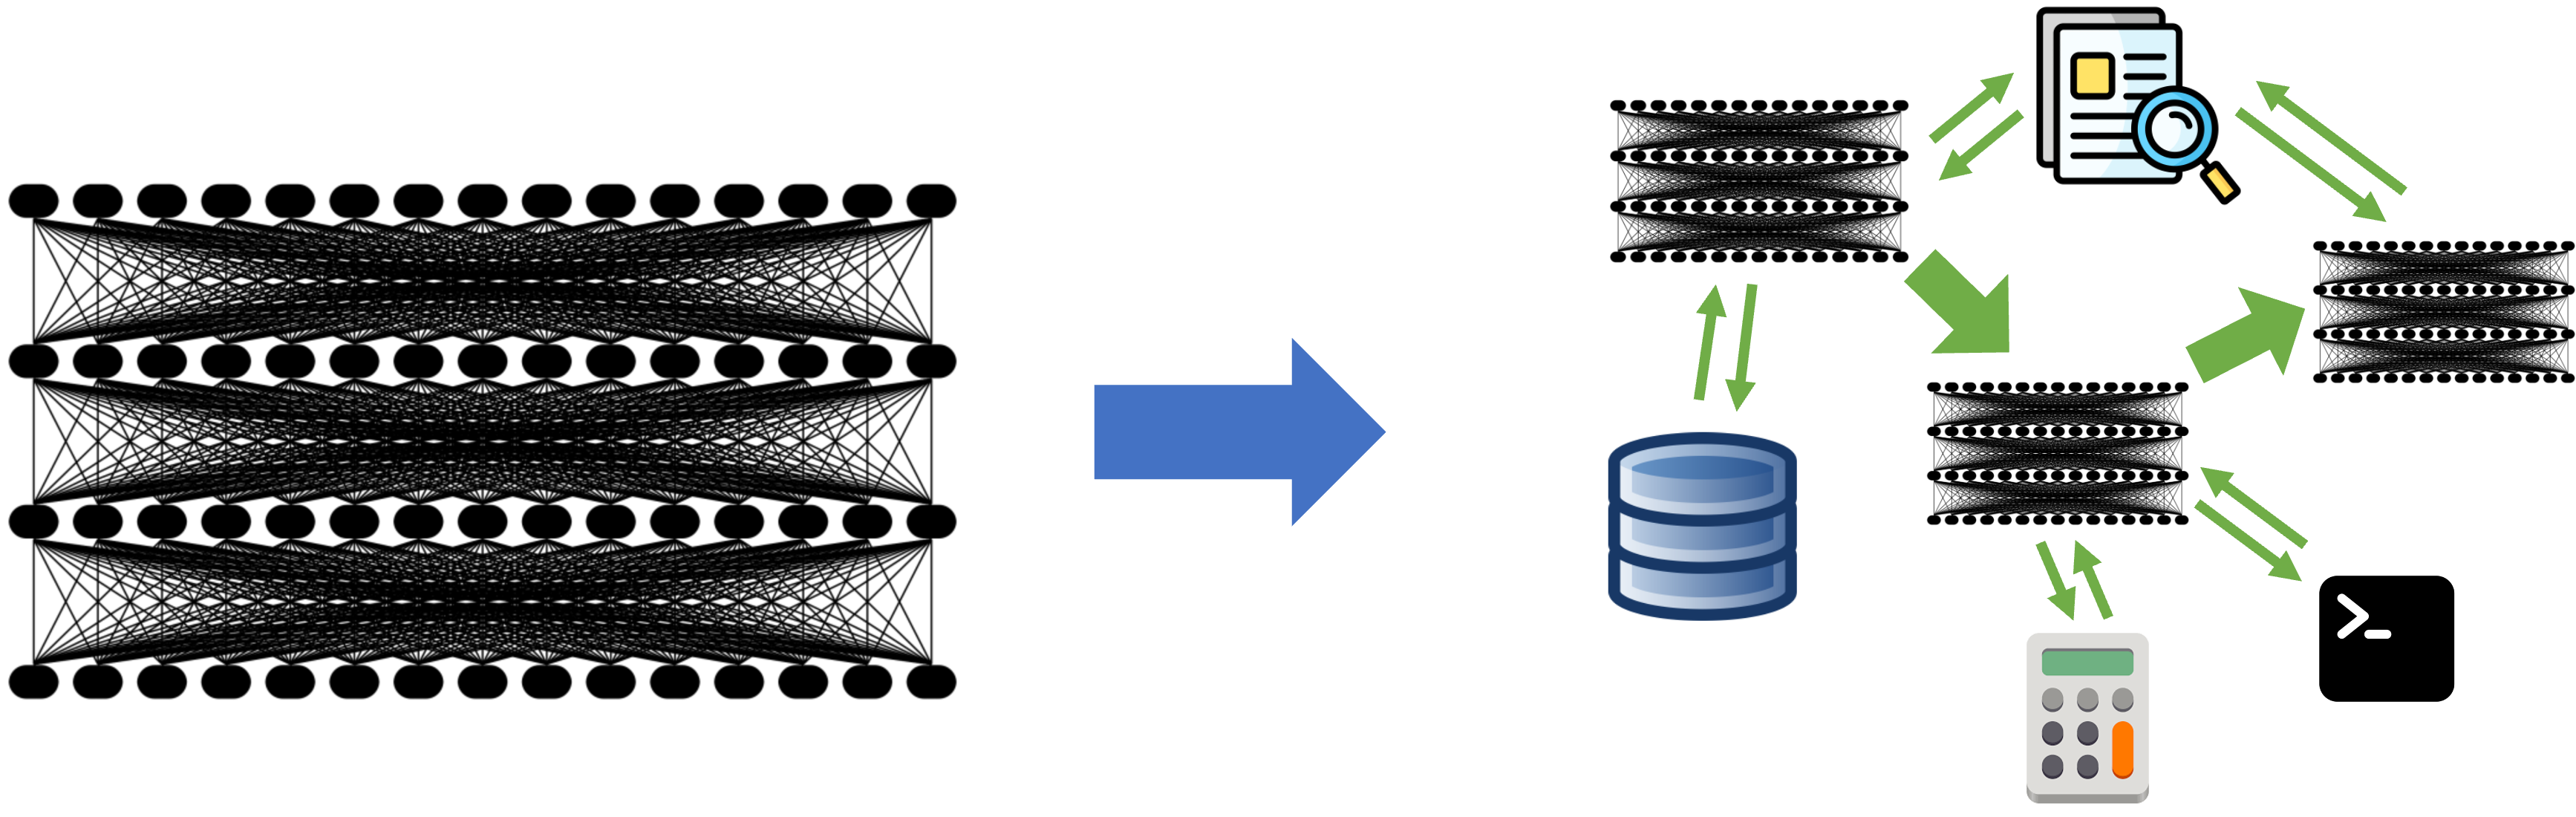
The article argues that leading AI results are increasingly produced by compound AI systems: applications that combine multiple model calls with retrieval systems, symbolic solvers, code execution, search, or other tools. It distinguishes these systems from a single statistical model and uses examples including AlphaCode 2, AlphaGeometry, Medprompt, Gemini’s CoT@32 evaluation strategy, and retrieval-augmented generation. The authors say system design can improve application quality more quickly and cheaply than scaling training alone, while also enabling access to current data, tighter behavioral control, citations, verification, and task-specific cost and latency tradeoffs. They note that compound systems introduce a large design space, requiring developers to allocate budgets across retrievers, models, and repeated calls. Optimization is difficult because components such as search engines and code interpreters are often non-differentiable, so conventional end-to-end neural-network training is insufficient. Operations also become harder because teams must monitor traces, intermediate outputs, data pipelines, security, and variable tool use. The article surveys composition frameworks and inference strategies, including LangChain, LlamaIndex, agent frameworks, Guardrails, chain-of-thought, self-consistency, and RAG. It presents DSPy as a framework for automatically optimizing LLM pipelines against a target metric, and FrugalGPT as a router that selects model cascades under quality or budget constraints. The authors also discuss AI gateways and LLMOps and DataOps tools for routing, tracing, evaluation, and monitoring. They conclude that compound systems are likely to remain a leading way to improve the quality and reliability of AI applications, although their best design practices remain an open research and engineering problem.